Offline Meta-Reinforcement Learning in Piecewise Stationary Environments

Abstract
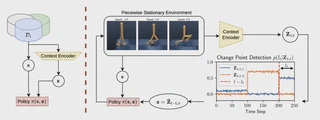
Adapting policies in piecewise stationary environments - where the underlying properties remain stable for periods but abruptly change at unknown points - remains a challenge in reinforcement learning (RL). Addressing this problem using context-based offline meta-RL, which enables generalization to new online tasks from offline data, is particularly appealing, as it avoids the risks associated with online exploration. These methods encode transition history (the context) into a task representation and condition the policy and value function to enable generalization. We show that existing approaches relying on a fixed-length context window face an inherent trade-off between rapid adaptation and inferring a stable task representation in piecewise stationary settings. We overcome this limitation by detecting task changes online from the temporal evolution of task representations and selectively retaining relevant transitions, yielding an adaptive context length. Experiments on continuous control benchmarks demonstrate that our approach enables faster adaptation and stable task identification, resulting in higher-performing policies compared to baselines. Code is available at https://github.com/MohammadrezaNakhaei/CAMEL-official.
Type
Publication
In Transactions on Machine Learning Research
